Batch Inference is now generally available on Serverless. It’s for jobs where nobody is waiting on each response: backfills, eval runs or embedding a large set of documents. Send the batch to the endpoint you already run, using your existing model and container. Runpod works through it on dedicated workers so your live traffic isn’t affected.
Because you’re not paying for speed, a batch costs up to 30% less than on-demand (20% less on H100, H200, B200 and B300). A batch can take hours, and results won’t arrive in order. You’ll get a console Inbox notification or a webhook when it finishes, fails or gets cancelled.
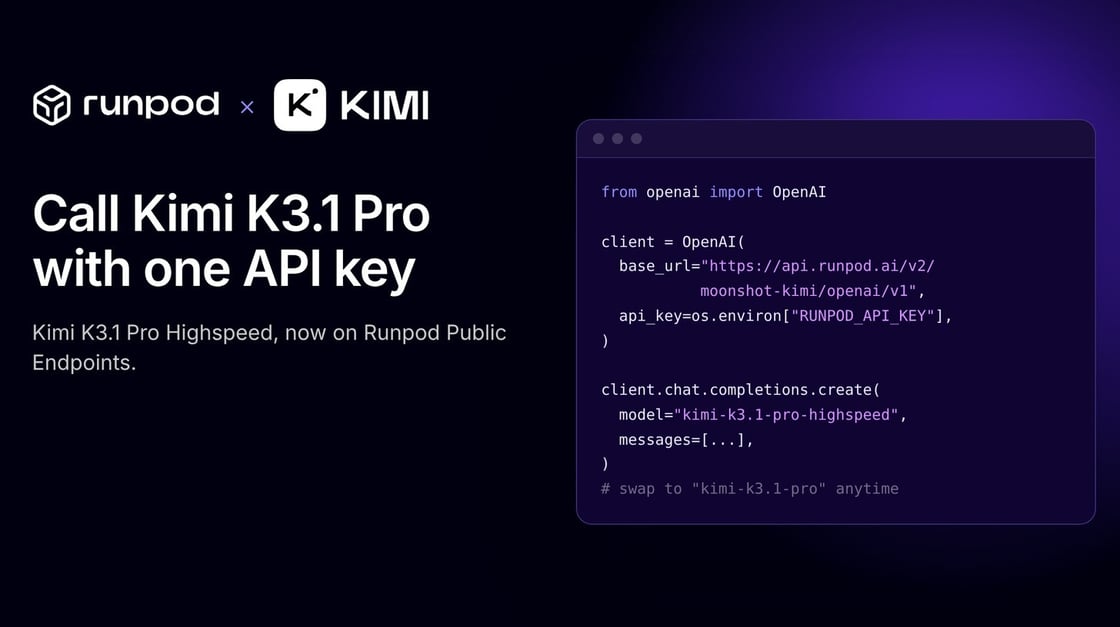
Kimi K3.1 Pro from Moonshot AI is live on Runpod Public Endpoints. This is a 3T-class open-weight model with a 1M token context window, at $2 per 1M input and $10 per 1M output tokens.
There's also a K3.1 Pro Highspeed variant that runs 2-3X faster for latency-sensitive work, like interactive coding and agent loops. Run it at $4 per 1M input and $20 per 1M output.
Both are OpenAI-compatible. If your code already uses the OpenAI SDK, point it at Runpod and change the model name. There’s no GPU to manage.
REST API v1 stops serving traffic on November 15. Calls to it will fail after that date. Existing v1 traffic is already rate limited, and those limits tighten this week. REST API v2 has long-term support, and the migration guide maps each v1 call to its v2 equivalent.
A preview template for NVIDIA’s 74B model, with model weights included and an OpenAI-compatible API. For experimentation; live GPU testing is still pending.