|
|
|
|
Ollama now supports speech models on macOS, with support for Windows and Linux coming soon. The first speech model is Phonon, a family of small, state-of-the-art text-to-speech (TTS) models from Gradium.
|
|
|
|
|
|
|
|
Once you download or upgrade Ollama to version 0.40.11, run a speech model:
|
|
|
ollama run phonon "Hello from Ollama."
|
|
|
|
Choose from dozens of voices with --voice:
|
|
|
ollama run phonon --voice Hugh "Once upon a time, a little alpaca lived at the top of a very tall mountain."
|
|
|
|
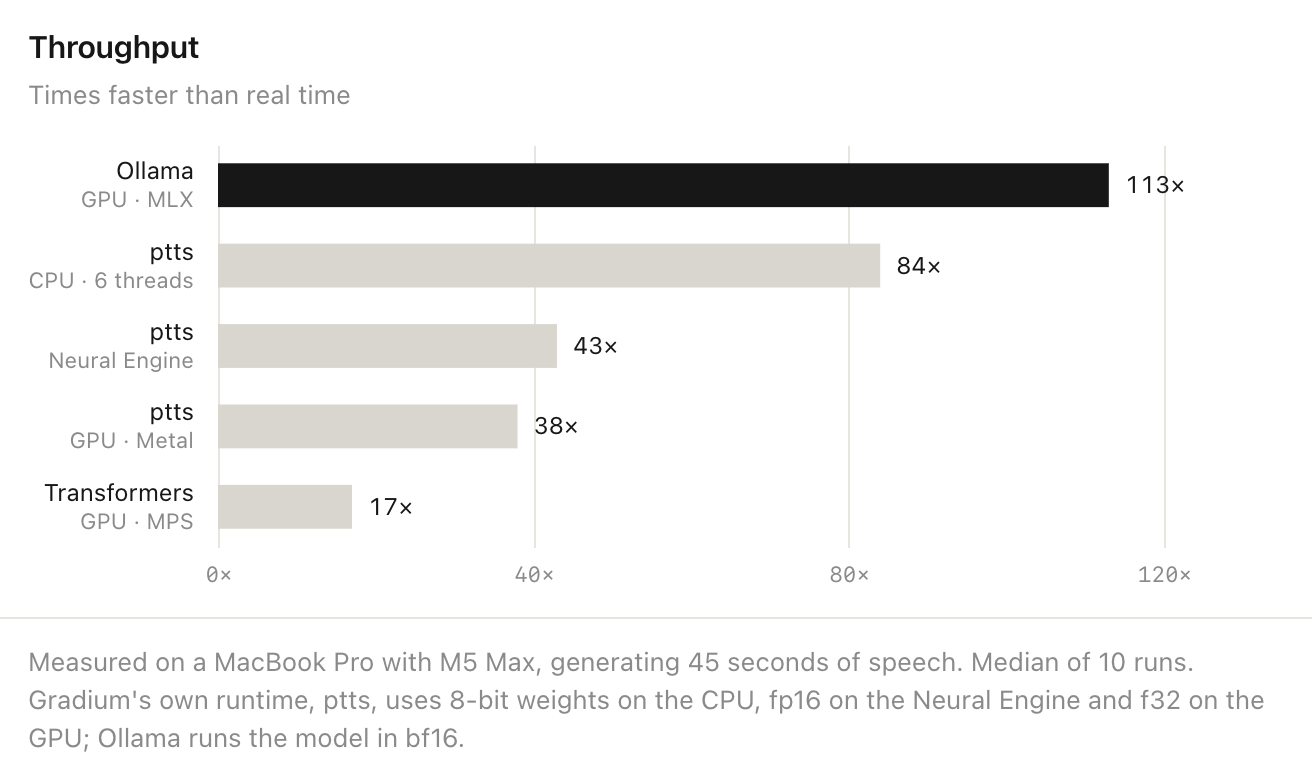
Accelerated by MLX, Ollama runs Phonon 35% faster than the next fastest option on a MacBook Pro with M5 Max, with the same accuracy as the reference implementation.
|
|
|
|
|
|
|
|
|
|
Apps can use it through the OpenAI-compatible /v1/audio/speech endpoint. You can also pipe in a chat model’s reply and hear it as it’s written:
|
|
|
ollama run gemma4 --hidethinking "Tell me a fun fact about owls in two sentences." | ollama run phonon
|
|
|
|
Hear the voices and learn more:
|
|
|
|
|
|
|
|
|
|
❤️ Ollama
|
|
|