Hi [First name],
You can now publish directly to alphaXiv! Today, Mistral published their Mistral Large 4 technical report and Intology published their latest blog on automating molecular discovery directly on alphaXiv.
Submission is lightning quick and doesn’t require an endorsement, while community signals help your work reach the right audience. This works well alongside submitting to arXiv: once your paper appears there, we can merge the two alphaXiv pages on our side.
Upcoming events
|
alphaXiv in Mumbai
Join alphaXiv’s first Paper Club Meetup in Mumbai as we begin building a strong research community in the city. Researchers across fields and anyone getting started in AI research are welcome.
Sign Up Here
|
Faster LLMs with Discrete Diffusion
Friday, November 13th 10:00-11:00 AM PT
New work from Cerebras Systems and IFM uses discrete diffusion to speed up LLM generation by up to 3× without sacrificing the base model’s quality. First author Subham Sahoo will walk through Uno, how it generates multiple tokens in parallel without a separate draft model, and what this means for serving LLMs at scale.
Sign Up Here
|
|
Trending papers
|
View all
|
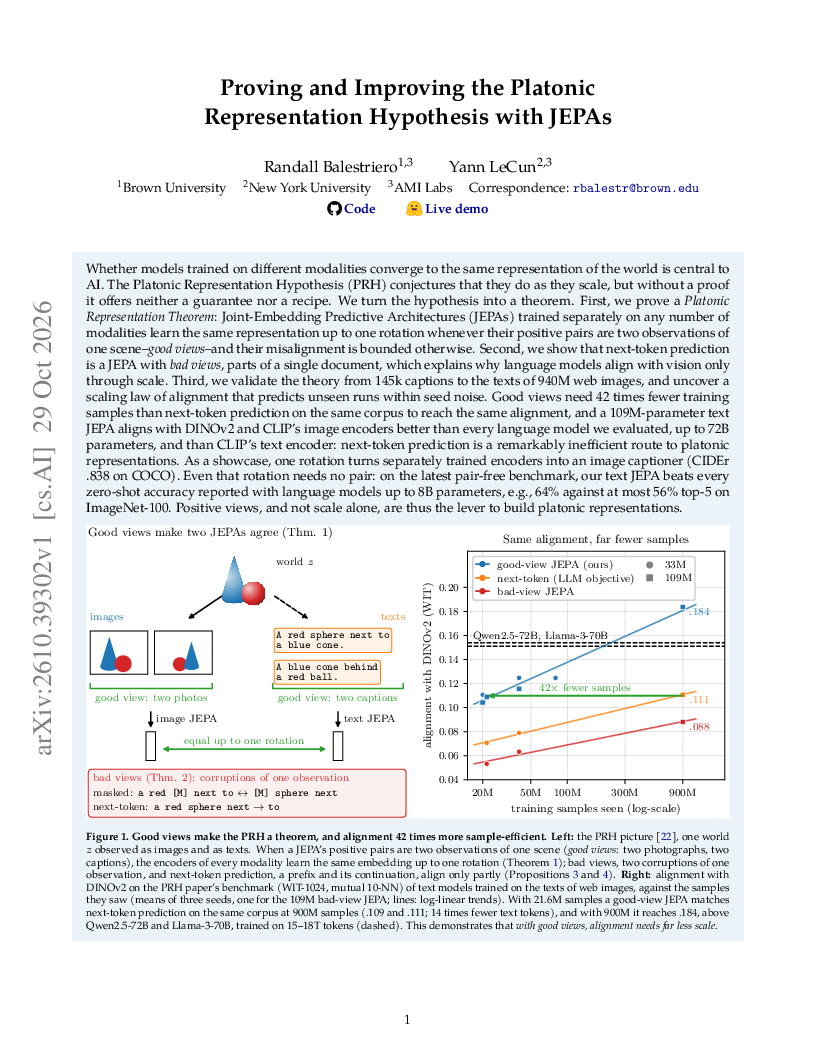
Proving and Improving the Platonic Representation Hypothesis with JEPAs
The paper formalizes how independently trained representations can align across modalities: under idealized conditions, JEPAs trained on the same positive-pa...
42,811 views
| |
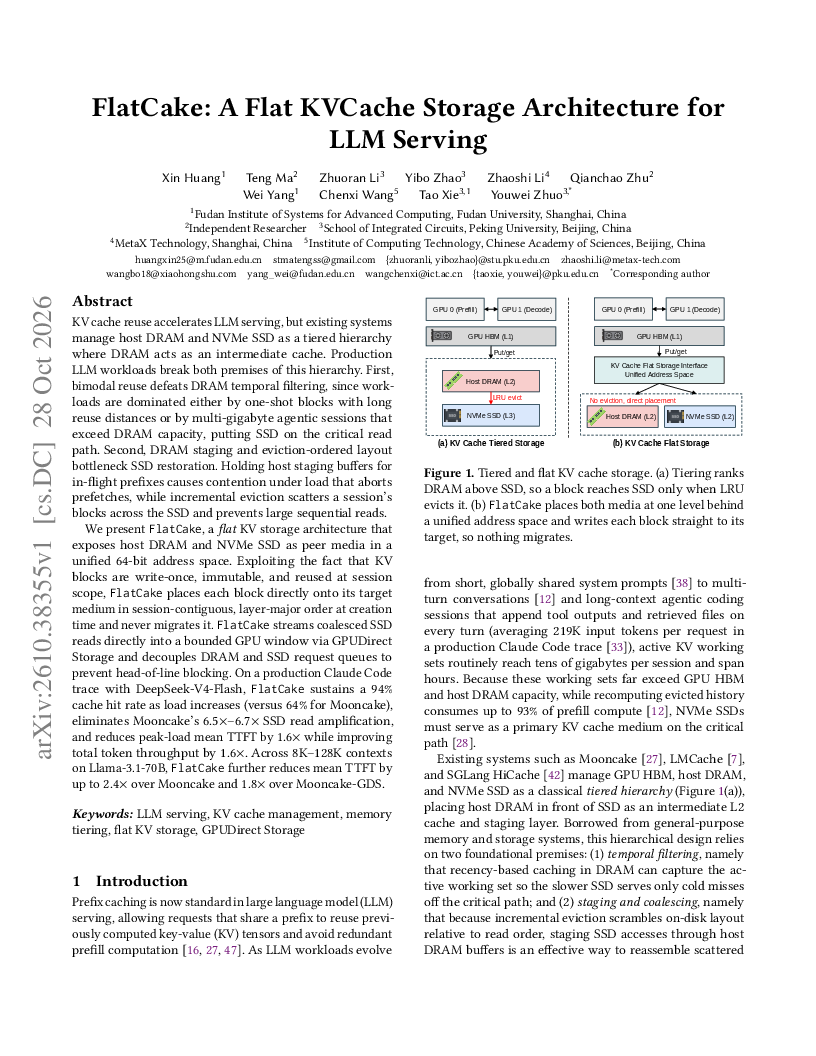
FlatCake: A Flat KVCache Storage Architecture for LLM Serving
KV cache reuse accelerates LLM serving, but existing systems manage host DRAM and NVMe SSD as a tiered hierarchy where DRAM acts as an intermediate ca...
5,188 views
|
|
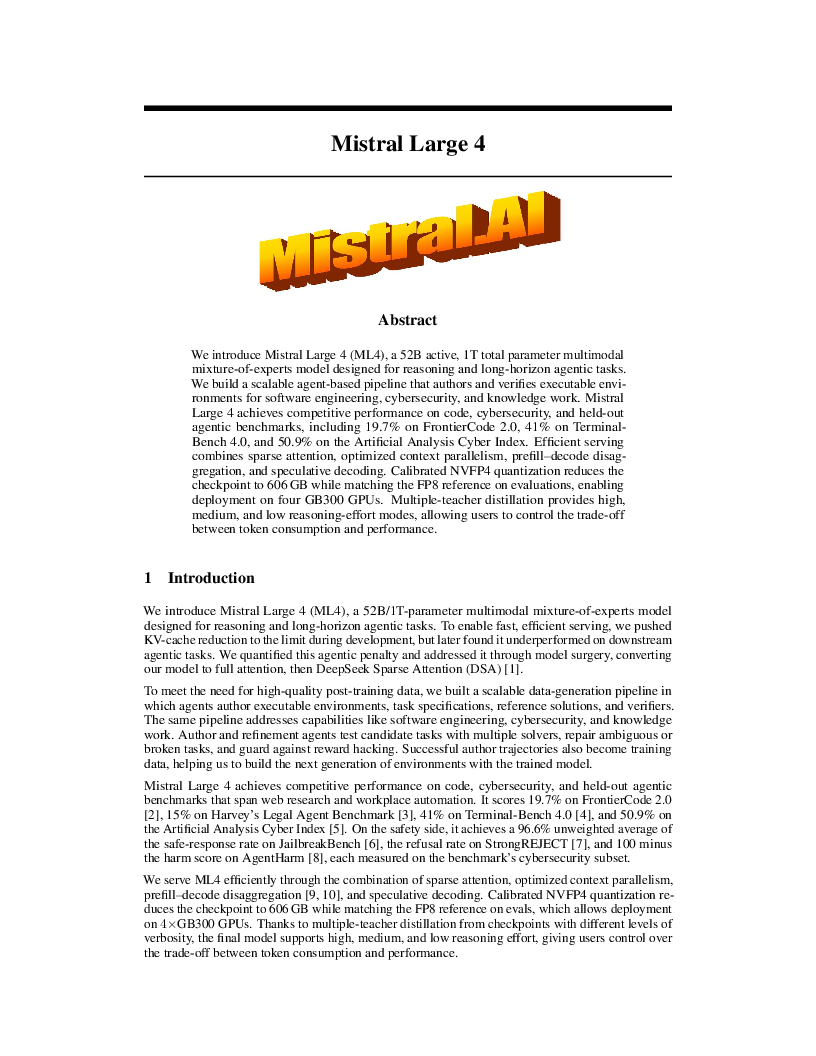
Mistral Large 4
We introduce Mistral Large 4 (ML4), a 52B active, 1T total parameter multimodal mixture-of-experts model designed for reasoning and long-horizon agent...
5,880 views
| |
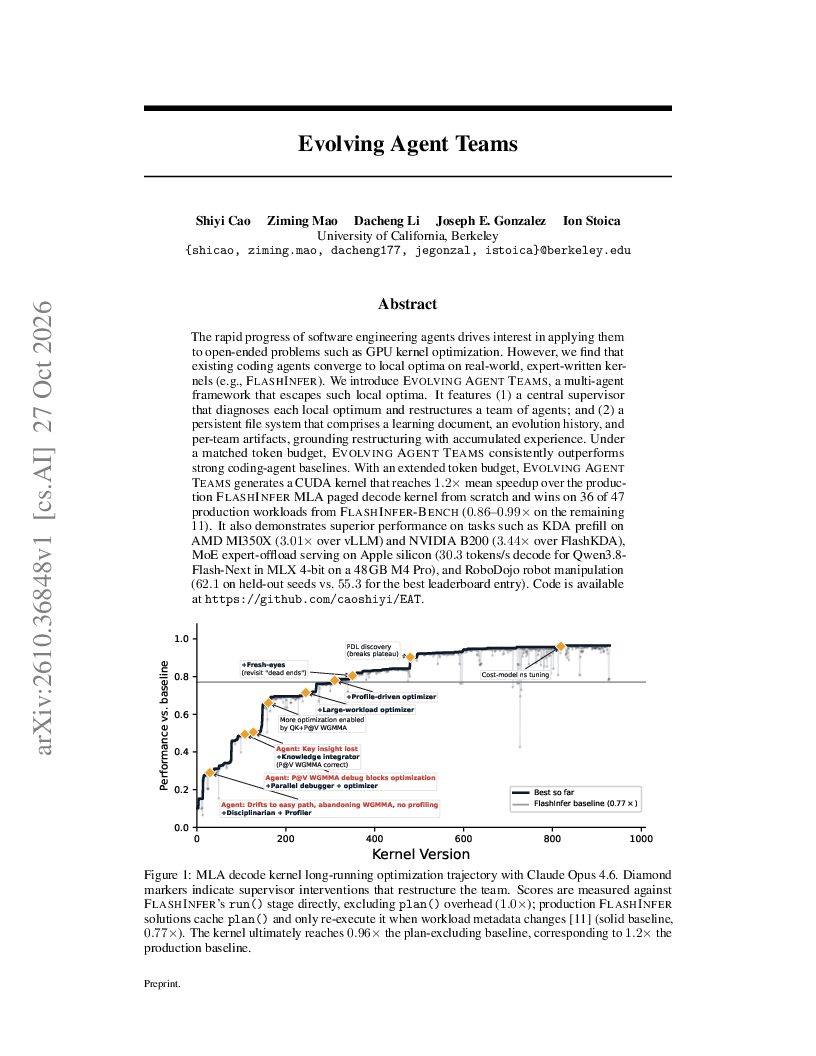
Evolving Agent Teams
The rapid progress of software engineering agents drives interest in applying them to open-ended problems such as GPU kernel optimization. However, we...
2,425 views
|
|
The Exponential Time Hypothesis Is False
The manuscript claims a deterministic, polynomial-space algorithm that exactly counts satisfying assignments of every fixed-width CNF in subexponential time...
23,510 views
| |
Training Foundation Models with a Single Algorithm
Foundation models are typically trained in stages: pretraining, midtraining, supervised fine-tuning (SFT), and reinforcement learning (RL), with chang...
2,127 views
|
|
|
 Follow