This week, we launched the You.com Extract API, a new endpoint that fetches and parses web pages and PDFs from a URL and returns clean markdown or HTML. On LlamaIndex's ParseBench-2, You.com Extract scored at least 80% higher for PDF parsing accuracy than Exa Contents and Parallel Extract.
Use Extract alongside web search when your agent needs the full document instead of snippets or highlights, or independently when you already have a URL. For PDFs, Extract goes beyond text-only parsing. The default parse_effort=standard runs a deeper parsing pass to recover tables, charts, forms, and scanned pages that text-only parsers can miss. |
80% Higher PDF Parsing Accuracy |
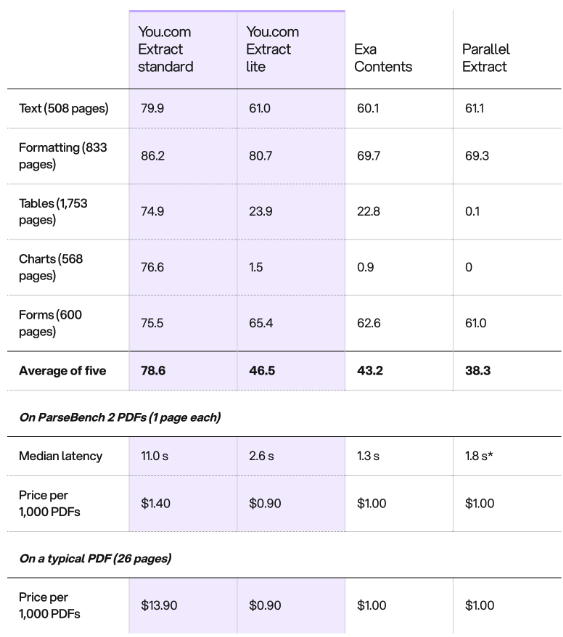
We evaluated Extract against Exa Contents and Parallel Extract using ParseBench-2, LlamaIndex's public document-parsing benchmark, across 3,782 PDF pages. Here's how Extract Standard compared: |
Extract Standard scored 78.6 when averaged across all five dimensions, compared to 43.2 for Exa and 38.3 for Parallel, which is 80% higher than Exa and more than twice as high as Parallel. It scored highest across all five measures, with the biggest differences in tables and charts. |
What does that look like on an actual PDF? |
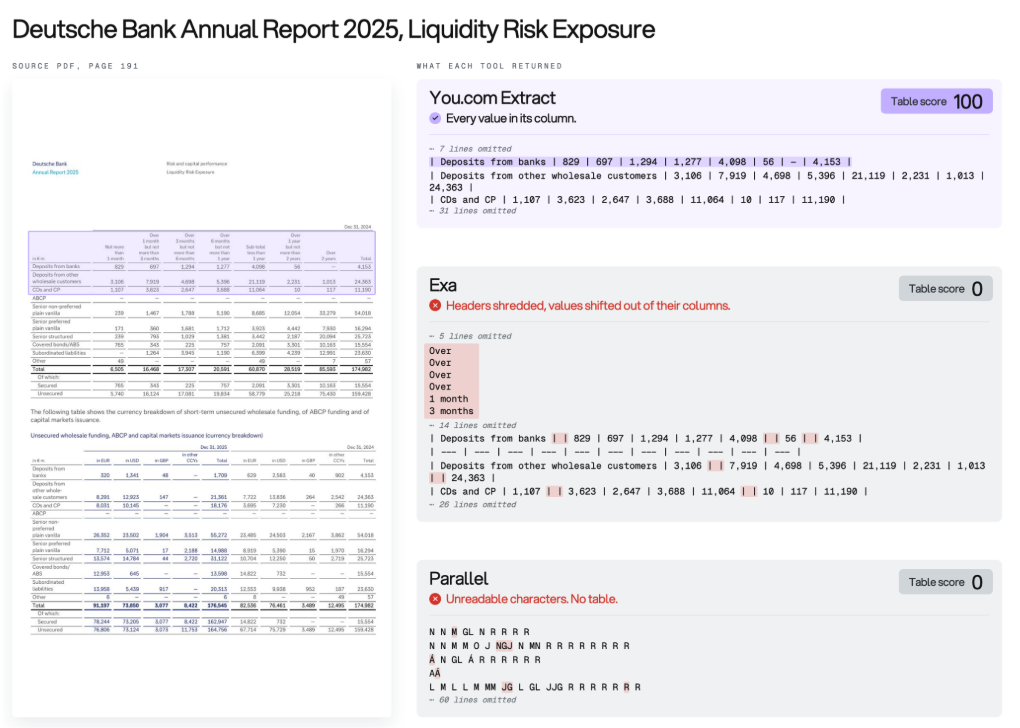
Take a liquidity risk table from Deutsche Bank's 2025 annual report. The table has eight columns, and keeping the values aligned with the correct headers is essential for retrieving accurate information. |
We ran the same page through all three APIs: |
-
You.com Extract: Returned both tables with their rows, columns, and values intact. Scored 100.
- Exa Contents: Broke the column headers into fragments and shifted values into the wrong columns. Scored 0.
- Parallel Extract: Returned unreadable characters instead of a usable table. Scored 0.
|
Only Extract preserved the table structure and values needed to reliably use the data. |
Choose the right parsing setting for your workload |
Not every PDF needs the same level of parsing. Extract gives you two parse_effort settings so you can choose based on the content you're processing. |
- standard (default): Deeper PDF parsing for tables, charts, forms, and scanned pages. $0.90 per 1,000 URLs + $0.50 per 1,000 PDF pages.
- lite: Faster text-layer extraction without the deeper parsing pass. $0.90 per 1,000 URLs, with no per-page fee.
|
Both settings fetch and parse web pages at the same price. On ParseBench-2, Lite also scored higher on average than Exa and Parallel, making it an option for text-based PDF workloads where speed and cost matter more than deeper parsing.
Install the official You.com MCP server to use Extract on web pages (and web search) for free, with no key or authentication required. |
Happy building, The You.com Team
|
|
|
|
© 2025 You.com. All rights reserved |
|
|
|
|
|