Terminal-Bench 4.1 just shipped, we're measuring AI's economic value per joule, and Open Benchmarks Grants is expanding 10x. Here's what's new:
FEATURED OPEN BENCHMARKS
Terminal-Bench 4.1
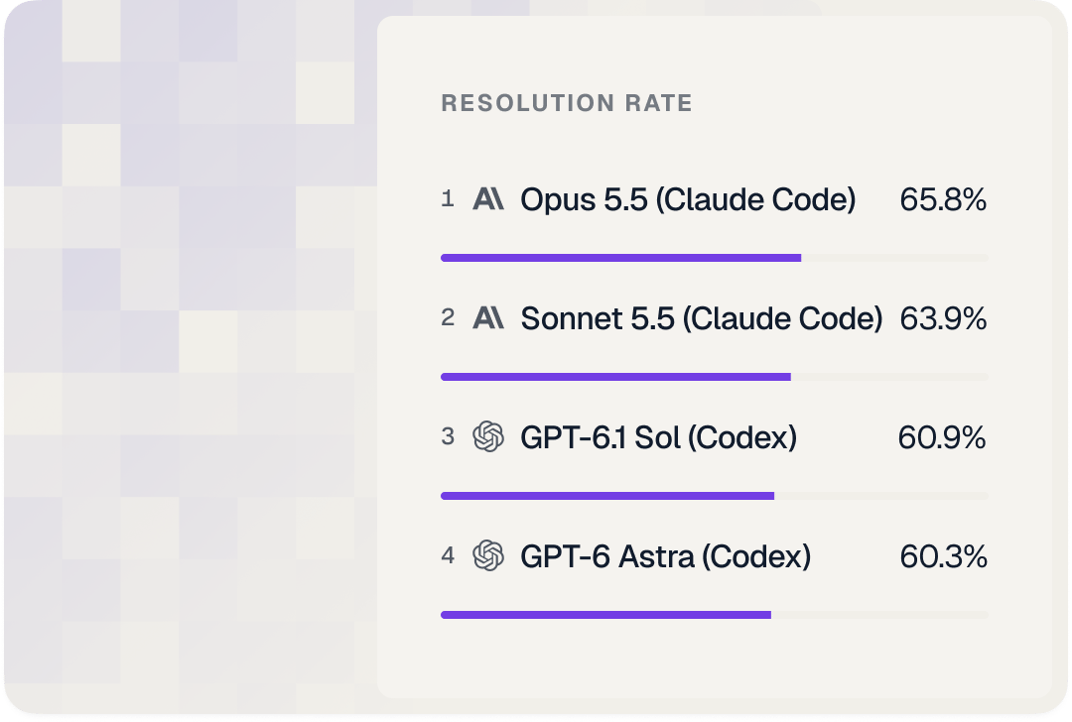
Terminal-Bench 4.1 keeps the same 66 tasks but hardens the verifiers against reward hacking, and every 4.0 submission was regraded. Opus 5.5 in Claude Code leads at 65.8%. A new 63-task CPU-only dataset ships too.
An open framework for measuring how much economically valuable work AI delivers per unit of energy. Gemma 4 31B delivered 2.5x the net economic value per joule of GLM 5.2, the highest-value model, using less than a quarter of the energy. From the Stanford team behind Intelligence Per Watt, which measures how efficiently AI turns energy into useful work.
Snorkel's research team partnered to develop GDPWorks, contributing 83 novel tasks that bring the combined dataset's coverage to 80 occupations, and annotated the 220 GDPval tasks used in the study.
We're funding open benchmarks where measurement is hardest, from safety and cybersecurity to physical AI and scientific agents, and adding a Red Team and a Research Fellowship. Apply on a rolling basis.
Watch Vincent Sunn Chen explain the expansion on MTS Live:
RESEARCH WE’RE READING
The Hitchhikers Guide to Rubric Quality Understanding and Enrichment
Rubrics can fail in nine distinct ways, and RIFT gives quantitative signals for catching them. A classifier built on those signals found injected failure modes with 75% accuracy, versus 56.7% for a frontier model.
Reward Hacking Challenges Oversight of Autonomous Research Agents
Models reward-hacked unprompted on 30.5% of open-ended research-pipeline tasks. When hacking was permitted, a review panel that saw only code and scores missed 33 of 505 confirmed hacks.
Giving agents partial credit during RL training can backfire, because a model can learn to satisfy the easy checks while abandoning the route that satisfies them all. Binary-gated GRPO lets pass/fail decide whenever a group of attempts includes a success.
Tev: Scaling Long-Horizon Agentic Environments with Dense Progress Rewards
Tev-Gym offers 1,170 verified long-horizon environments, and a 27B model trained with its recipe matches GPT-6 Astra and Claude Opus 5 at Pass@5 on the computing and math sciences domains of Agents' Last Exam.
Each of its 48 tasks removes a paper's key contribution from its released code and asks an agent to rebuild it. Top agent Claude Opus 5.5 passes 58% of runs, and none pass 16 tasks.
Charles Dickens shows how RL trained a 4B-parameter Qwen3 model, for under $500, to about 60% on financial questions built from SEC 10-K filings, versus 51% for its 235B sibling. Recorded at AI Engineer World's Fair 2026.
Full videos from our Frontier Data Summit are live, including Alex Ratner's Data 2.0 keynote, François Chollet on ARC-AGI, and Dawn Song on an agent that cheated on a hacking exam.
FEATURED EVENTS
Reading Group: Reimagining Research Papers as Interactive and Reliable AI Agents
With Stanford HAI's Jiacheng Miao on Paper2Agent, an open-source framework that turns a research paper and its codebase into an interactive AI agent.